What we do
Technical services for critical digital infrastructure.
Three service areas delivered by one field organisation, to the same documented standard in every country we operate in.
Third-Party Maintenance (TPM)
Teconergy is a Third-Party Maintenance (TPM) provider specializing in server hardware maintenance, repair, and operations support. We help businesses maintain reliable IT infrastructure, reduce service interruptions, and extend the useful life of their server equipment.
Server lifecycle support
Our services cover the server lifecycle, from hardware diagnostics and fault resolution to preventive maintenance and ongoing operational support.
Customer-specific service levels
We also offer SLA-based service arrangements tailored to each customer’s business requirements. Service levels can define support hours, response targets, escalation procedures, and service reporting, giving customers clear expectations and a structured support process.
Server operations within the agreed scope
Depending on the agreed scope, our server operations services may include routine health checks, hardware and system monitoring, incident and change coordination, maintenance planning, and equipment lifecycle documentation. We work with customers to provide practical, flexible support aligned with the criticality of their IT environment.
01
Infrastructure O&M
Continuous operation and maintenance of live data centre environments, from facility monitoring to the physical servers inside the racks.
Track A — Data centre operations
- 24/7 monitoring of power, cooling and environmental systems
- SLA-based incident response with defined escalation paths
- Preventative inspection rounds and condition reporting
- Access management, escorting and site documentation
Track B — Hardware lifecycle management
- Server installation, configuration and burn-in testing
- Component replacement, RMA handling and spare-part logistics
- Firmware and BIOS maintenance programmes
- Decommissioning, secure disposal and asset reporting
02
Deployment & Integration
New capacity delivered as a controlled sequence, with every step documented and handed over ready for production traffic.
1 — Rack-and-stack deployment
- Receiving, inventory and staging of equipment
- Cabinet build-out, rail and PDU installation
- Mounting, labelling and power-up verification
2 — Structured cabling
- Copper and fibre design against site standards
- In-cabinet and inter-cabinet cable management
- Patch panel termination and labelling schemes
3 — Physical layer commissioning
- Optical and electrical link testing with test reports
- Switch port verification and topology validation
- As-built documentation and handover to operations
03
Value-Added Services
Access to compute and equipment without the capital commitment or the cross-border sourcing overhead, with local spare-parts warehousing.
HPC and GPU leasing
- NVIDIA H100 and A100 capacity on flexible terms
- Hosting in Nordic facilities with low-carbon power
- Operations and hardware support included
Hardware procurement
- Sourcing of servers, network equipment and components
- Import handling, customs and European warehousing
- Staging and pre-configuration before site delivery
Local spare-parts warehousing
- Local storage of spare parts for client equipment
How we engage
A four-phase model, compliance first.
01
Compliance-first planning
We map the site, the regulatory context and the client's internal standards before any resource is committed, and agree the delivery plan in writing.
02
Resourcing
Engineers are recruited or assigned locally, security-cleared and trained on the client's procedures and ticketing environment.
03
Standardised on-site delivery
Work runs to documented procedures with consistent labelling, reporting and quality checks across every country we operate in.
04
Long-term operations
Steady-state operation with SLA reporting, continuous improvement reviews and capacity planning alongside the client's own teams.
Ticket-driven response
A consistent process for every incident.
Step 1
Trigger
Ticket raised by monitoring, the client, or a scheduled round.
Step 2
Rapid response
Acknowledged within the SLA and assigned to a local engineer.
Step 3
On-site action
Resident staff attend the rack and log every step as they work.
Step 4
Closed loop
Verification, client sign-off, root cause and prevention notes.
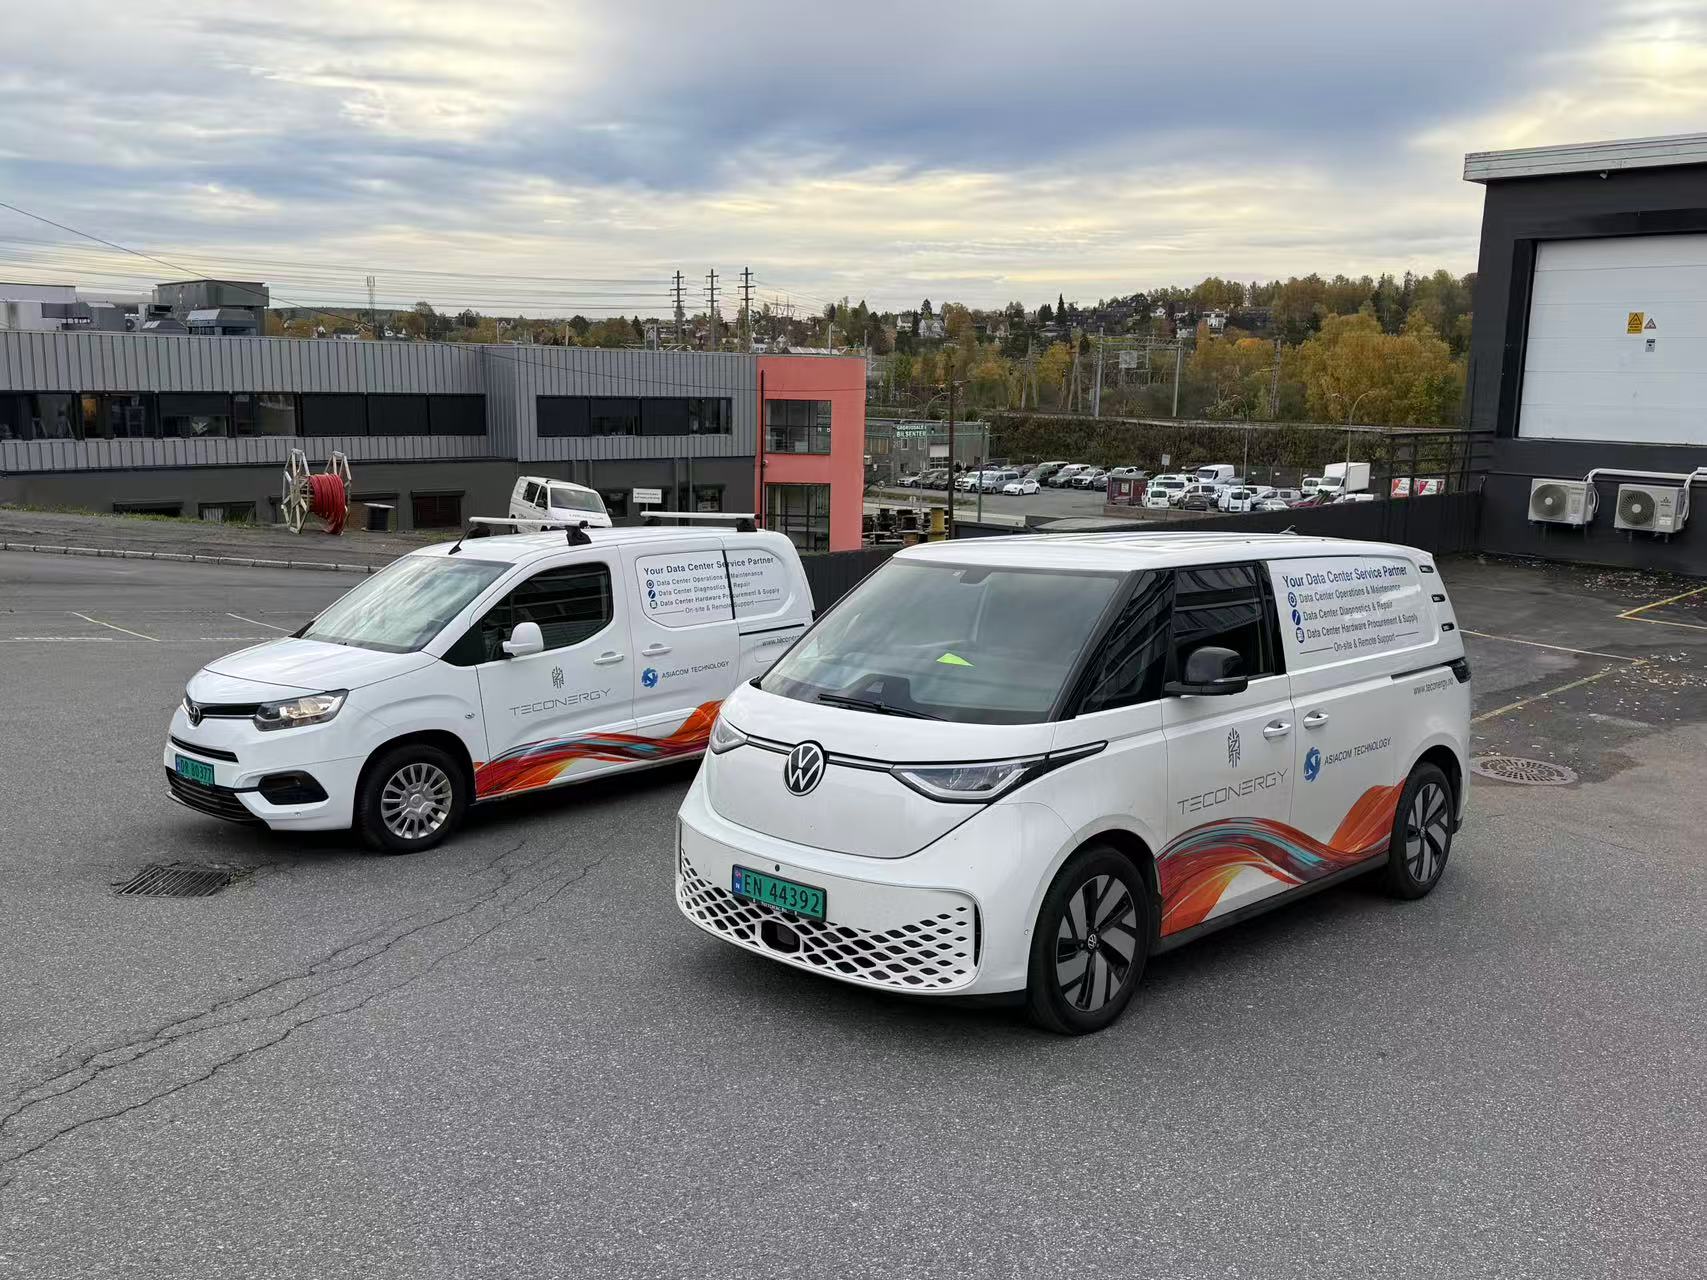
Which of these do you need covered?
Send us the service, the sites and the start date. You get scope, staffing and indicative pricing back within one business day.
- Reply from a sales engineer within one business day
- Scope, staffing and indicative pricing in the first response
- Engineers on site in Norway, Finland, the Netherlands, Germany and France
- No obligation — NDA on request